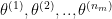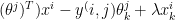Building an Agentic Stock Picker with Anthropic

For the past two years I have been hearing a lot about agentic flows. Yet all my work with AI-assisted coding has been deterministic task flows, for high-performance, scalable systems.

So I decided to try my hand at the agentic approach, and build an agentic stock picker. The idea was that the application would download data for stocks, get the fundamental and technical indicators along with the news items for each stock, and then have agents:

  • filter the stocks down on the fundamental and technical indicators
  • read the news items and try to identify why a stock price was dropping or growing
  • come up with a final list — stocks to buy, stocks to watch, and stocks to avoid

The approach was to use regular python to

  • download four years of prices, statements news, and compute every indicator, fundamental and technical namely ROE, ROCE, P/E, RSI, MACD, volatility and the rest
  • filter ~500 companies down to 15, on those numbers alone
  • checks every claim the agents make against the frozen data, and deletes the ones the data contradicts
  • scores whatever survives, and produces the final buy / watch / avoid list

and agents

  • argue about one company at a time with one agent for the business, one for the price chart, one for the news
  • and every claim has to come with the condition that would prove it wrong
  • then a second model attacks the claims that survived, and can only attack — there is no field in its answer for agreeing

Agentic Stock Picker

The dashboard of the Agentic Stock Picker is shown below
On the left we have

  • Sliders: the sliders to choose fundamental and technical ratios to filter on
  • Max candidates to recommend
  • Model: Offline heurestic/Anthropic/Qwen 14b( TBD)
  • Ceiling (USD):
  • Compile spend plan: This option will give the spend estimate and the hard stop
  • Approve and Run : If the amount is fine we can approve the run
  • Past runs: The results of past runs can be selected here
A screenshot of a financial analysis interface displaying stock data, including symbols, ratings, scores based on fundamental and technical analysis, and various financial metrics.

Design Strategy

Governance is the backbone of the implementation.

The agents run offline. When a model is running, there is no network. When the network is live, there is no model.

The network being live and a running model is never true

Text describing the first pillar titled 'Sealed window', highlighting network access during a specific phase.

The goal of the agent-based approach was to put the agents under a strict governance plan. In fact the whole design is built around governing them.

The agents never touch the market data provider at all. The download happens first, in ordinary Python with no model involved, over a fixed list of seven read-only URLs using a single read-only Upstox analytics token. By the time an agent starts, that connection is closed, the token has been dropped from the environment, and the process the agent runs in cannot even import the code that would talk to Upstox. This is least privilege enforced structurally rather than promised.

So the agents cannot reach the market, cannot trade, and cannot see a portfolio. There is no order, holdings or funds code path anywhere in the repository. While a model is running, exactly one address is reachable: the model provider itself.

The budget works the same way. The full cost of a run is computed and approved before the first call, and every call has to claim a one-use ticket against it. Going over budget is not something the system detects and recovers from. A call without a ticket cannot be made at all.

Everything follows from one invariant: the market-data connection and a running model are never live at the same time. Data is collected first and frozen; analysis then runs in a separate process with no route back to the provider. The seal enforces this in both directions — the data network cannot open while a model is running, and a model cannot start while the data network is live.

Collection issues exactly seven read-only GET requests: the NSE instrument master, daily and intraday candles, key ratios, the income statement, the balance sheet, and news by instrument. Every path segment and query parameter is typed and matched in full, so a permitted template cannot be bent into another resource. During analysis the models read the frozen snapshot, may call four probe tools for deeper price history, full statements, peer ranks and further news, and may emit claims that each carry a machine-checkable disproof condition.

No model computes any number and every ranking is fixed arithmetic in Python. Spending is prepaid: the committed total is the hard stop, approved by hash before the first call, with a one-use ticket per request. Every request and model call is recorded in an append-only, hash-chained log.

Controls are fail-closed. A violation stops the run; there is no path that retries around it or falls back to something less governed.

The seven allowlisted reads

#CapabilityHostPath template
1instrument_masterassets.upstox.com/market-quote/instruments/exchange/NSE.json.gz
2daily_candlesapi.upstox.com/v3/historical-candle/{instrument_key}/days/1/{to_date}/{from_date}
3intraday_daily_candleapi.upstox.com/v3/historical-candle/intraday/{instrument_key}/days/1
4key_ratiosapi.upstox.com/v2/fundamentals/{isin}/key-ratios
5income_statementapi.upstox.com/v2/fundamentals/{isin}/income-statement
6balance_sheetapi.upstox.com/v2/fundamentals/{isin}/balance-sheet
7news_by_instrumentapi.upstox.com/v2/news

The parameters are part of the allowlist, not just the paths

Every segment is typed by full-match regex where the instrument_key must be NSE_EQ\|<ISIN>, dates must be YYYY-MM-DD, isin must match the ISIN shape. So the path template alone can’t be bent into another resource.

Query params are typed too, and required where it matters:

  • income_statement — type=consolidated (required), time_period=yearly|quarterly (required)
  • balance_sheet — type=consolidated (required)
  • news_by_instrument — category=instrument_keys (required), instrument_keys (required, up to 30 per request), page_number/page_size optional, capped at 100

Rule one: The model works offline

Market data is downloaded first, saved to disk, and locked. Subsequently AI starts and by that point the program has no route to the market data provider at all. The two never overlap.

Flowchart depicting the interaction between Market Data and an AI Model during various stages of data processing, including collection, filtering, claiming, checking, attacking, and publishing.

This holds whichever model you use. With Claude, the one address reachable while a model runs is the Anthropic API with a model served on your own machine it is 127.0.0.1

Rule two: every claim carries its own disproof

This is the heart of the design. When the model says something, it must also say what would make that statement false which is written as a short formula the computer can evaluate against the saved data.

Text display of financial metrics: ROCE at 47.79% against a sector benchmark of 14.99% and ROE at 36.8% compared to a sector average of 13.06%. Status indication for evaluation criteria.

The claim is “ROCE stands at 47.79% versus…” and the disproof or falsifier is
roce_pct < sector_roce_pct +5. Since the ROCE (Return on Capital Equity) is not less tan sector_roce_pct +5, this falsifier turns out false i.e. 47.79 is not less than 19.99. Because the disproof is false the claim survives.

A table outlining a process with steps related to computing financial metrics like ROCE and RSI, specifying who performs each step, including Python and a model.
Flowchart illustrating the four ways a claim can be invalidated, including steps for checking evidence and conditions for refutation or survival.

Here are some examples of how claims and falsifiers work

A comparison of claims related to company performance metrics, showcasing a correct claim that survives verification and a wrong claim that has been correctly refuted.

The six steps, in order

A run is six phases. Only two of them contain a model, and the market-data connection is closed in five of the six. The figures below are from the live run of 18 September 2026.

1. Collect and freeze (market data: connected model: idle)

This is the only step with a live connection, and no model is anywhere near it. It is ordinary Python making a fixed set of read-only calls.

For each of the roughly 500 companies in the Nifty 500, seven things are fetched. The instrument master, to resolve the company to its ISIN. Four years of daily candles, 1,460 calendar days back from the run date, which works out at about 992 trading sessions per company. Today’s session separately, from the intraday endpoint, because the daily series does not include it until the market closes. Six headline ratios with their sector benchmarks: PE, PB, ROE, ROA, ROCE and EV/EBITDA. The income statement twice, once yearly and once quarterly. The balance sheet. And recent news, where the request asks for a 30 day window but the provider returns roughly a week.

None of the technical indicators come from the provider. RSI, MACD, the moving averages, ATR, volatility, the volume ratio, the returns and the drawdown are all computed here in Python from the candles just downloaded. The same goes for the fundamental derivations: operating margin and its year on year delta, leverage and its delta, the growth rates, the bank ratios. The provider supplies raw material, and every number a model later reasons about is arithmetic this code did itself. That matters because a model asked to compute an average will happily produce a plausible one.

Then the connection is closed, the token is dropped from the environment, the process is sealed, and only then is anything written to disk. That ordering is deliberate. Nothing is persisted while a route to the outside still exists.

The snapshot is seven files: the candles, the raw fundamentals, the news, the instrument records, the computed indicator rows, the evidence index, and a manifest. Each file is written to a temporary path, made read-only, and then moved into place atomically, so a snapshot is never half written. The directory itself is read-only too. The manifest records the hash of every file, and the directory is named after the hash of the manifest. Loading a snapshot re-hashes all seven files and compares them against the manifest before returning anything. Change one digit in one file and the load raises an integrity error rather than running.

That is why it is fingerprinted. The reason is not tamper-proofing so much as reproducibility. A dossier cites a snapshot hash, a screen config hash and a spend plan hash. Given those three, the same run produces the same output, which is what makes “why did it say that?” a question with an answer.

The evidence index is the part that matters most for what the agents do later. Every fact is packaged as an evidence record, and that run has 4,252 of them across nine kinds:

KindCountWhat it holds
key_ratios498the six ratios with sector values
fundamental_derived498the full 26 column computed row
technical_derived498the full 21 column computed row
income_statement_yearly498four years of results
income_statement_quarterly498four quarters
balance_sheet498assets and liabilities by period
price_history498the 30 most recent closes and volumes, plus the session count
news_derived498the headline counts
news_article268individual headlines, summaries truncated to 600 characters

Each record carries its own identifier, of the form ev: followed by sixteen hex characters, derived by hashing the API call that produced it, its parameters, the as-of date, and the row it came from. It also keeps the name of the capability that fetched it and the exact parameters used, so any fact can be traced back to the specific call that produced it.

Those identifiers are the only way anything downstream is permitted to refer to a fact. When an analyst writes a claim in step 3, it must cite evidence IDs, and the validator rejects any ID that is not in this index or that belongs to a different company. It is a chain of custody: every sentence in the final report traces to a claim, every claim to one or more evidence IDs, and every ID to a row in a file whose hash is recorded in a manifest that names the directory.

One consequence worth noticing. An analyst never sees the 992 candles. It sees the computed indicator row, which was calculated from all of them, plus the 30 most recent closes. The heavy data stays on disk; only the derived view reaches a prompt.

2. Filter down to a shortlist (market data: closed model: idle)

This step is plain Python. There is no model in it anywhere, which is also why the slider settings can never leak into a prompt: there is no prompt here to leak into.

It runs in two stages, and they work quite differently. The first is a pass or fail gate. The second is a ranking.

Stage one, the gate. Seven thresholds were active for this run:

SliderSetting
ROE floor12 percent
ROCE floor12 percent, non-banks only
Revenue growth floor0 percent
P/E ceiling80
RSI band30 to 80
ATR ceiling5 percent of price
Candidates kept15

Each is compared straight against the saved number for that company. 498 companies in, 192 out, 306 rejected.

Two refusals are built into that gate. If a filter is switched on and the number it needs is missing, the company is rejected rather than waved through. And if the data is too old to trust, judged per dimension against a freshness limit, it is rejected even when every other number looks perfect. Missing data never gets the benefit of the doubt.

Some filters are scoped by company type. The ROCE floor and the leverage ceiling apply only to non-banks, because those measures are meaningless for a bank, whose balance sheet is supposed to be mostly other people’s money. There is a separate Net NPA ceiling that applies to banks only, which I did not switch on for this run.

Stage two, the ranking. The 192 survivors are then scored on fourteen measures grouped into five themes:

Table detailing investment metrics categorized by group: Quality, Value, Growth, Trend, and Risk, with corresponding weights and measures.

The top 15 go forward; the other 177 are dropped, and the report states that number rather than leaving it implied.

Two deliberate refusals: a company missing a required number is rejected, never given the benefit of the doubt, and a company whose accounts are too old to trust is rejected even if every other number looks perfect.

3. Ask for arguments (market data: closed model: thinking)

Each of the 15 companies gets three separate questions, asked independently, each seeing only its own slice of the frozen data: one about the business (Claude Sonnet 5), one about the price chart (Sonnet 5), one about the news (the cheaper Haiku 4.5). The agent is handed the real numbers, not a summary of them.

Fundamental: PE, PB, ROE, ROA, ROCE, EV/EBITDA and the sector benchmark for each, revenue and profit growth, operating margin and its one year delta, leverage (liabilities over equity) and its delta, the bank ratios (NIM, Net NPA, CASA and their sector benchmarks) when is_bank is 1, and fundamentals_age_days. Twenty six columns in all.

Technical: close, SMA20/50/200 and the price against each as a percentage, RSI-14, MACD with its signal and histogram, ATR-14 and ATR%, 20 day annualised volatility, 20 day volume ratio, 5 day, 30 day, 90 day and 1 year returns, drawdown from the 52 week high, and last_candle_age_days. Twenty one columns.

News: the raw headlines, up to 25, most recent first, plus news_count_7d and news_count_window.

Each analyst returns at most six claims. Every one carries evidence references, a confidence between 0.05 and 0.95, a written justification, and, the part that matters, the condition that would prove it wrong.

The three analysts never see each other’s work, and none of them sees another company. Each also has to stay in its lane when writing that condition: a fundamental claim can only be tested against fundamental columns, a technical claim only against technical ones. The news analyst is the one exception and may reach for the price columns, because there are only two news columns and both are just counts, so a claim like “this headline explains the fall” would have nothing to be tested against otherwise.

There is a toolbox in the code that would let an analyst ask for more of the frozen data, such as deeper price history, the full statement tables, or how the company ranks against its peers. It is written but not wired up. Each agent still gets exactly one call and cannot ask for anything more, and the budget sets aside thirty probe calls per run that can never fire. It is on the list to either connect properly or delete.

What the models cannot do is reach the market data provider, read your files, run code, or call each other. While a model is running, the only address reachable is the model provider itself. News text is wrapped and labelled as data, with a note that nothing inside it is an instruction. That envelope is not really the defence, though. A headline can still persuade a model. The defence is the next step, where every claim is checked against numbers the headline cannot touch.

4. Check every argument (market data: closed model: idle)

No model runs here. Plain code reads each claim’s disproof condition, plugs in the saved numbers, and gets a straight yes or no. If the condition turns out to be true, the claim is wrong and it is deleted — not softened, not down-weighted. Nothing about the model’s tone or confidence can save it. A claim is also discarded if it cites evidence about another company, quotes a figure that appears nowhere in the data, cannot be evaluated, or sets a test that could never fail.

Survivors are then scored by simple addition: each contributes its confidence, positive claims adding and negative claims subtracting, weighted by subject — business 1.0, price chart 0.8, news 0.5. News counts least on purpose: it is the one input written by strangers. In the 18 September run, 137 claims went in and 127 came out.

5. Let an auditor attack market data: closedmodel: thinking

A second model, Sonnet 5 again but on the highest thinking setting and with by far the largest token budget in the run, goes through the claims that survived and tries to destroy them.

It works in batches of three companies at a time, so five batches for a run of 15. For each batch it sees two things. First, the claims themselves: the statement, its direction, the falsifier, and the evidence IDs cited. It does not see the analyst’s justification or reasoning, so it cannot be anchored by the argument that produced the claim. Second, the evidence: every computed indicator row for those companies, plus any specific record a claim cited.

That second part is the interesting bit. The auditor gets a wider view than the analyst whose claim it is attacking. The business analyst only ever saw the fundamental columns, and the chart analyst only the technical ones. The auditor sees the whole computed row, so it can cross check a claim against figures the original analyst never had to reconcile. A bullish claim about margins can be attacked with the price trend, and a bullish claim about the chart can be attacked with the balance sheet.

Its power is deliberately one sided. The output schema has no field for agreement, no way to endorse a claim or raise its confidence. There is nothing it can return except attacks. And every attack carries its own falsifier and is checked exactly like a claim, so an attack that cannot be tested is thrown out on the same rule as everybody else.

The useful consequence is that a broken or overzealous auditor can only ever make the system quieter. It can remove a pick. It can never add one.

6. Publish what survivedmarket data: closedmodel: idle

No model writes the report. It is assembled from surviving claims, so every sentence traces to a claim, every claim to a fact, and every fact to a row in the frozen data. The disproof conditions stay attached, so a reader can see what would make each argument wrong. The 18 September run published fourteen companies: ten to watch, four to avoid, and no buys.

A flowchart illustrating a process with six steps, including data collection, filtering, argument requests, claims checks, auditor evaluations, and publishing results. Each step is color-coded and linked, with annotations for specific tasks like 'Sonnet 5' and 'Haiku 4.5.'

A) Stock Picks

The shortlist itself, as one table: symbol, the call, the total score, the three dimension subtotals for business, chart and news, and how many claims survived for that company. Fourteen rows for this run, the ten to watch and the four to avoid.

A screenshot of an NSE research tool displaying various stock metrics, including fundamental and technical scores for multiple stocks, along with recommended actions like 'WATCH' or 'AVOID'. The layout shows a snapshot titled 'SEALED WINDOW' with selections for filters and criteria adjustments.

B) Why- the justification

Pick a company from the dropdown and read the surviving claims that produced its score, each shown with its confidence, its direction, and the condition that would have killed it. This is the tab that answers “why did it say that”, and every line traces back to a row in the frozen data

Screenshot of an analytics dashboard focusing on financial metrics, including ROE floor, liabilities, and revenue growth, with various performance indicators and spend plan results.

C) Fundamental analysis

The business claims, one company at a time from the dropdown, because across fifteen companies these run to dozens of rows. Each shows the statement, the model’s own justification, and the falsifier it was tested against.

Screenshot of a financial analysis dashboard displaying key metrics for company performance, including ROCE, liabilities, net profit growth, and earnings growth. The section features a spend plan compilation interface with sliders for candidate selection.

D) Technical Analysis

The same for the price chart claims, read the same way, one company at a time.

Screenshot of a trading analysis tool displaying financial metrics and results related to a stock or asset, including performance indicators and a run summary.

E) News analysis
The news claims, shown whole rather than per company, because there are only a handful. Most companies produced none at all: the provider returned no headlines for the majority of the universe in the window.

A screenshot of a financial analysis tool showing data on stock performance, including metrics such as ROE, liabilities, and various forecast claims for different companies.

Next steps

  1. The current data from Upstox does not allow for walk forward evaluation as the ratios are not dated. I will see if I can get data from other sources which provide more detailed granualar data
  2. Use the entire stock universe of ~2K stocks instead of just Nifty 500 from NSE directly instead.
  3. Use open models Qwen 8B or 14B models as the current runs with Sonnet, Haiku cost money. This will require me to host the Qwen on my Mac

Also see

  1. Sea shells on the seashore
  2. Deep Learning from first principles in Python, R and Octave – Part 3
  3. The Science of Innovation
  4. Presentation on “Intelligent Networks, CAMEL protocol, services & applications”

Player Performance Estimation using AI Collaborative Filtering

1. Introduction

Often times before crucial matches, or in general, we would like to know the performance of a batsman against a bowler or vice-versa, but we may not have the data. We generally have data where different batsmen would have faced different sets of bowlers with certain performance data like ballsFaced, totalRuns, fours, sixes, strike rate and timesOut. Similarly different bowlers would have performance figures(deliveries, runsConceded, economyRate and wicketTaken) against different sets of batsmen. We will never have the data for all batsmen against all bowlers. However, it would be good estimate the performance of batsmen against a bowler, even though we do not have the performance data. This could be done using collaborative filtering which identifies and computes based on the similarity between batsmen vs bowlers & bowlers vs batsmen.

This post shows an approach whereby we can estimate a batsman’s performance against bowlers even though the batsman may not have faced those bowlers, based on his/her performance against other bowlers. It also estimates the performance of bowlers against batsmen using the same approach. This is based on the recommender algorithm which is used to recommend products to customers based on their rating on other products.

This idea came to me while generating the performance of batsmen vs bowlers & vice-versa for 2 IPL teams in this IPL 2022 with my Shiny app GooglyPlusPlus in the optimization tab, I found that there were some batsmen for which there was no data against certain bowlers, probably because they are playing for the first time in their team or because they were new (see picture below)

In the picture above there is no data for Dewald Brevis against Jasprit Bumrah and YS Chahal. Wouldn’t be great to estimate the performance of Brevis against Bumrah or vice-versa? Can we estimate this performance?

While pondering on this problem, I realized that this problem formulation is similar to the problem formulation for the famous Netflix movie recommendation problem, in which user’s ratings for certain movies are known and based on these ratings, the recommender engine can generate ratings for movies not yet seen.

This post estimates a player’s (batsman/bowler) using the recommender engine This post is based on R package recommenderlab

“Michael Hahsler (2021). recommenderlab: Lab for Developing and Testing Recommender Algorithms. R package version 0.2-7. https://github.com/mhahsler/recommenderlab”

Note 1: Thw data for this analysis is taken from Cricsheet after being processed by my R package yorkr.

You can also read this post in RPubs at Player Performance Estimation using AI Collaborative Filtering

A PDF copy of this post is available at Player Performance Estimation using AI Collaborative Filtering.pdf

You can download this R Markdown file and the associated data and perform the analysis yourself using any other recommender engine from Github at playerPerformanceEstimation

Problem statement

In the table below we see a set of bowlers vs a set of batsmen and the number of times the bowlers got these batsmen out.
By knowing the performance of the bowlers against some of the batsmen we can use collaborative filter to determine the missing values. This is done using the recommender engine.

The Recommender Engine works as follows. Let us say that there are feature vectors x^1, x^2 and x^3 for the 3 bowlers which identify the characteristics of these bowlers (“fast”, “lateral drift through the air”, “movement off the pitch”). Let each batsman be identified by parameter vectors \theta^1, \theta^2 and so on

For e.g. consider the following table

Then by assuming an initial estimate for the parameter vector \theta and the feature vector xx we can formulate this as an optimization problem which tries to minimize the error for \theta^T*x This can work very well as the algorithm can determine features which cannot be captured. So for e.g. some particular bowler may have very impressive figures. This could be due to some aspect of the bowling which cannot be captured by the data for e.g. let’s say the bowler uses the ‘scrambled seam’ when he is most effective, with a slightly different arc to the flight. Though the algorithm cannot identify the feature as we know it, but the ML algorithm should pick up intricacies which cannot be captured in data.

Hence the algorithm can be quite effective.

Note: The recommender lab performance is not very good and the Mean Square Error is quite high. Also, the ROC and AUC curves show that not in aLL cases the algorithm is doing a clean job of separating the True positives (TPR) from the False Positives (FPR)

Note: This is similar to the recommendation problem

The collaborative optimization object can be considered as a minimization of both \theta and the features x and can be written as

J(x^{(1)},x^{(2)},..x^{(n_{u})}, \theta^{(1)},\theta^{(2)},..,\theta^{(n_{m})}}= 1/2\sum(\theta^{j})^{T}x^{i}- y^{(i,j)})^{2} + \lambda\sum\sum (x_{k}^{i})^{2} + \lambda\sum\sum (_\theta{k}^{j})^{2}

The collaborative filtering algorithm can be summarized as follows

  1. Initialize \theta^1, \theta^2… \theta^{n_{u}} and the set of features be x^1,x^2, … ,x^{n_{m}} to small random values
  2. Minimize J(\theta^1, \theta^2… \theta^{n_{u}},x^1, x^2, … ,x^{n_{m}}) using gradient descent. For every
    j=1,2, …n_{u}, i= 1,2,.., n_{m}
  3. x_{k}^{i} := x_{k}^{i} – \alpha ( \sigma (\theta^j)^T)x^i – y^(i,j)\theta_{k}^{j} + \lambda x_{k}^i

    &

    \theta_{k}^{i} := \theta_{k}^{i} – \alpha ( \sigma (\theta^j)^T)x^i - y^(i,j)\theta_{k}^{j} + \lambda x_{k}^i
  4. Hence for a batsman with parameters \theta and a bowler with (learned) features x, predict the “times out” for the player where the value is not known using \theta^Tx

The above derivation for the recommender problem is taken from Machine Learning by Prof Andrew Ng at Coursera from the lecture Collaborative filtering

There are 2 main types of Collaborative Filtering(CF) approaches

  1. User based Collaborative Filtering User-based CF is a memory-based algorithm which tries to mimics word-of-mouth by analyzing rating data from many individuals. The assumption is that users with similar preferences will rate items similarly.
  2. Item based Collaborative Filtering Item-based CF is a model-based approach which produces recommendations based on the relationship between items inferred from the rating matrix. The assumption behind this approach is that users will prefer items that are similar to other items they like.

1a. A note on ROC and Precision-Recall curves

A small note on interpreting ROC & Precision-Recall curves in the post below

ROC Curve: The ROC curve plots the True Positive Rate (TPR) against the False Positive Rate (FPR). Ideally the TPR should increase faster than the FPR and the AUC (area under the curve) should be close to 1

Precision-Recall: The precision-recall curve shows the tradeoff between precision and recall for different threshold. A high area under the curve represents both high recall and high precision, where high precision relates to a low false positive rate, and high recall relates to a low false negative rate

library(reshape2)
library(dplyr)
library(ggplot2)
library(recommenderlab)
library(tidyr)
load("recom_data/batsmenVsBowler20_22.rdata")

2. Define recommender lab helper functions

Helper functions for the RMarkdown notebook are created

  • eval – Gives details of RMSE, MSE and MAE of ML algorithm
  • evalRecomMethods – Evaluates different recommender methods and plot the ROC and Precision-Recall curves
# This function returns the error for the chosen algorithm and also predicts the estimates
# for the given data
eval <- function(data, train1, k1,given1,goodRating1,recomType1="UBCF"){
  set.seed(2022)
  e<- evaluationScheme(data,
                       method = "split",
                       train = train1,
                       k = k1,
                       given = given1,
                       goodRating = goodRating1)
  
  r1 <- Recommender(getData(e, "train"), recomType1)
  print(r1)
  
  p1 <- predict(r1, getData(e, "known"), type="ratings")
  print(p1)
  
  error = calcPredictionAccuracy(p1, getData(e, "unknown"))
  
  print(error)
  p2 <- predict(r1, data, type="ratingMatrix")
  p2
}
# This function will evaluate the different recommender algorithms and plot the AUC and ROC curves
evalRecomMethods <- function(data,k1,given1,goodRating1){
  set.seed(2022)
  e<- evaluationScheme(data,
                       method = "cross",
                       k = k1,
                       given = given1,
                       goodRating = goodRating1)
  
  models_to_evaluate <- list(
    `IBCF Cosinus` = list(name = "IBCF", 
                          param = list(method = "cosine")),
    `IBCF Pearson` = list(name = "IBCF", 
                          param = list(method = "pearson")),
    `UBCF Cosinus` = list(name = "UBCF",
                          param = list(method = "cosine")),
    `UBCF Pearson` = list(name = "UBCF",
                          param = list(method = "pearson")),
    `Zufälliger Vorschlag` = list(name = "RANDOM", param=NULL)
  )
  
  n_recommendations <- c(1, 5, seq(10, 100, 10))
  list_results <- evaluate(x = e, 
                           method = models_to_evaluate, 
                           n = n_recommendations)
  plot(list_results, annotate=c(1,3), legend="bottomright")
  plot(list_results, "prec/rec", annotate=3, legend="topleft")
}

3. Batsman performance estimation

The section below regenerates the performance for batsmen based on incomplete data for the different fields in the data frame namely balls faced, fours, sixes, strike rate, times out. The recommender lab allows one to test several different algorithms all at once namely

  1. User based – Cosine similarity method, Pearson similarity
  2. Item based – Cosine similarity method, Pearson similarity
  3. Popular
  4. Random
  5. SVD and a few others

3a. Batting dataframe

head(df)
##   batsman1         bowler1 ballsFaced totalRuns fours sixes  SR timesOut
## 1 A Badoni        A Mishra          0         0     0     0 NaN        0
## 2 A Badoni        A Nortje          0         0     0     0 NaN        0
## 3 A Badoni         A Zampa          0         0     0     0 NaN        0
## 4 A Badoni     Abdul Samad          0         0     0     0 NaN        0
## 5 A Badoni Abhishek Sharma          0         0     0     0 NaN        0
## 6 A Badoni      AD Russell          0         0     0     0 NaN        0

3b Data set and data preparation

For this analysis the data from Cricsheet has been processed using my R package yorkr to obtain the following 2 data sets – batsmenVsBowler – This dataset will contain the performance of the batsmen against the bowler and will capture a) ballsFaced b) totalRuns c) Fours d) Sixes e) SR f) timesOut – bowlerVsBatsmen – This data set will contain the performance of the bowler against the difference batsmen and will include a) deliveries b) runsConceded c) EconomyRate d) wicketsTaken

Obviously many rows/columns will be empty

This is a large data set and hence I have filtered for the period > Jan 2020 and < Dec 2022 which gives 2 datasets a) batsmanVsBowler20_22.rdata b) bowlerVsBatsman20_22.rdata

I also have 2 other datasets of all batsmen and bowlers in these 2 dataset in the files c) all-batsmen20_22.rds d) all-bowlers20_22.rds

You can download the data and this RMarkdown notebook from Github at PlayerPerformanceEstimation

Feel free to download and analyze the data and use any recommendation engine you choose

3c. Exploratory analysis

Initially an exploratory analysis is done on the data

df3 <- select(df, batsman1,bowler1,timesOut)
df6 <- xtabs(timesOut ~ ., df3)
df7 <- as.data.frame.matrix(df6)
df8 <- data.matrix(df7)
df8[df8 == 0] <- NA
print(df8[1:10,1:10])
##                 A Mishra A Nortje A Zampa Abdul Samad Abhishek Sharma
## A Badoni              NA       NA      NA          NA              NA
## A Manohar             NA       NA      NA          NA              NA
## A Nortje              NA       NA      NA          NA              NA
## AB de Villiers        NA        4       3          NA              NA
## Abdul Samad           NA       NA      NA          NA              NA
## Abhishek Sharma       NA       NA      NA          NA              NA
## AD Russell             1       NA      NA          NA              NA
## AF Milne              NA       NA      NA          NA              NA
## AJ Finch              NA       NA      NA          NA               3
## AJ Tye                NA       NA      NA          NA              NA
##                 AD Russell AF Milne AJ Tye AK Markram Akash Deep
## A Badoni                NA       NA     NA         NA         NA
## A Manohar               NA       NA     NA         NA         NA
## A Nortje                NA       NA     NA         NA         NA
## AB de Villiers           3       NA      3         NA         NA
## Abdul Samad             NA       NA     NA         NA         NA
## Abhishek Sharma         NA       NA     NA         NA         NA
## AD Russell              NA       NA      6         NA         NA
## AF Milne                NA       NA     NA         NA         NA
## AJ Finch                NA       NA     NA         NA         NA
## AJ Tye                  NA       NA     NA         NA         NA

The dots below represent data for which there is no performance data. These cells need to be estimated by the algorithm

set.seed(2022)
r <- as(df8,"realRatingMatrix")
getRatingMatrix(r)[1:15,1:15]
## 15 x 15 sparse Matrix of class "dgCMatrix"
##    [[ suppressing 15 column names 'A Mishra', 'A Nortje', 'A Zampa' ... ]]
##                                               
## A Badoni         . . . . . . . . . . . . . . .
## A Manohar        . . . . . . . . . . . . . . .
## A Nortje         . . . . . . . . . . . . . . .
## AB de Villiers   . 4 3 . . 3 . 3 . . . 4 3 . .
## Abdul Samad      . . . . . . . . . . . . . . .
## Abhishek Sharma  . . . . . . . . . . . 1 . . .
## AD Russell       1 . . . . . . 6 . . . 3 3 3 .
## AF Milne         . . . . . . . . . . . . . . .
## AJ Finch         . . . . 3 . . . . . . 1 . . .
## AJ Tye           . . . . . . . . . . . 1 . . .
## AK Markram       . . . 3 . . . . . . . . . . .
## AM Rahane        9 . . . . 3 . 3 . . . 3 3 . .
## Anmolpreet Singh . . . . . . . . . . . . . . .
## Anuj Rawat       . . . . . . . . . . . . . . .
## AR Patel         . . . . . . . 1 . . . . . . .
r0=r[(rowCounts(r) > 10),]
getRatingMatrix(r0)[1:15,1:15]
## 15 x 15 sparse Matrix of class "dgCMatrix"
##    [[ suppressing 15 column names 'A Mishra', 'A Nortje', 'A Zampa' ... ]]
##                                              
## AB de Villiers  . 4 3 . . 3 . 3 . . . 4 3 . .
## Abdul Samad     . . . . . . . . . . . . . . .
## Abhishek Sharma . . . . . . . . . . . 1 . . .
## AD Russell      1 . . . . . . 6 . . . 3 3 3 .
## AJ Finch        . . . . 3 . . . . . . 1 . . .
## AM Rahane       9 . . . . 3 . 3 . . . 3 3 . .
## AR Patel        . . . . . . . 1 . . . . . . .
## AT Rayudu       2 . . . . . 1 . . . . 3 . . .
## B Kumar         3 . 3 . . . . . . . . . . 3 .
## BA Stokes       . . . . . . 3 4 . . . 3 . . .
## CA Lynn         . . . . . . . 9 . . . 3 . . .
## CH Gayle        . . . . . 6 . 3 . . . 6 . . .
## CH Morris       . 3 . . . . . . . . . 3 . . .
## D Padikkal      . 4 . . . 3 . . . . . . 3 . .
## DA Miller       . . . . . 3 . . . . . 3 . . .
# Get the summary of the data
summary(getRatings(r0))
##    Min. 1st Qu.  Median    Mean 3rd Qu.    Max. 
##   1.000   3.000   3.000   3.463   4.000  21.000
# Normalize the data
r0_m <- normalize(r0)
getRatingMatrix(r0_m)[1:15,1:15]
## 15 x 15 sparse Matrix of class "dgCMatrix"
##    [[ suppressing 15 column names 'A Mishra', 'A Nortje', 'A Zampa' ... ]]
##                                                                       
## AB de Villiers   .         -0.7857143 -1.7857143 .  .       -1.7857143
## Abdul Samad      .          .          .         .  .        .        
## Abhishek Sharma  .          .          .         .  .        .        
## AD Russell      -2.6562500  .          .         .  .        .        
## AJ Finch         .          .          .         . -0.03125  .        
## AM Rahane        4.6041667  .          .         .  .       -1.3958333
## AR Patel         .          .          .         .  .        .        
## AT Rayudu       -2.1363636  .          .         .  .        .        
## B Kumar          0.3636364  .          0.3636364 .  .        .        
## BA Stokes        .          .          .         .  .        .        
## CA Lynn          .          .          .         .  .        .        
## CH Gayle         .          .          .         .  .        1.5476190
## CH Morris        .          0.3500000  .         .  .        .        
## D Padikkal       .          0.6250000  .         .  .       -0.3750000
## DA Miller        .          .          .         .  .       -0.7037037
##                                                                              
## AB de Villiers   .         -1.7857143 . . . -0.7857143 -1.785714  .         .
## Abdul Samad      .          .         . . .  .          .         .         .
## Abhishek Sharma  .          .         . . . -1.6000000  .         .         .
## AD Russell       .          2.3437500 . . . -0.6562500 -0.656250 -0.6562500 .
## AJ Finch         .          .         . . . -2.0312500  .         .         .
## AM Rahane        .         -1.3958333 . . . -1.3958333 -1.395833  .         .
## AR Patel         .         -2.3333333 . . .  .          .         .         .
## AT Rayudu       -3.1363636  .         . . . -1.1363636  .         .         .
## B Kumar          .          .         . . .  .          .         0.3636364 .
## BA Stokes       -0.6086957  0.3913043 . . . -0.6086957  .         .         .
## CA Lynn          .          5.3200000 . . . -0.6800000  .         .         .
## CH Gayle         .         -1.4523810 . . .  1.5476190  .         .         .
## CH Morris        .          .         . . .  0.3500000  .         .         .
## D Padikkal       .          .         . . .  .         -0.375000  .         .
## DA Miller        .          .         . . . -0.7037037  .         .         .

4. Create a visual representation of the rating data before and after the normalization

The histograms show the bias in the data is removed after normalization

r0=r[(m=rowCounts(r) > 10),]
getRatingMatrix(r0)[1:15,1:10]
## 15 x 10 sparse Matrix of class "dgCMatrix"
##    [[ suppressing 10 column names 'A Mishra', 'A Nortje', 'A Zampa' ... ]]
##                                    
## AB de Villiers  . 4 3 . . 3 . 3 . .
## Abdul Samad     . . . . . . . . . .
## Abhishek Sharma . . . . . . . . . .
## AD Russell      1 . . . . . . 6 . .
## AJ Finch        . . . . 3 . . . . .
## AM Rahane       9 . . . . 3 . 3 . .
## AR Patel        . . . . . . . 1 . .
## AT Rayudu       2 . . . . . 1 . . .
## B Kumar         3 . 3 . . . . . . .
## BA Stokes       . . . . . . 3 4 . .
## CA Lynn         . . . . . . . 9 . .
## CH Gayle        . . . . . 6 . 3 . .
## CH Morris       . 3 . . . . . . . .
## D Padikkal      . 4 . . . 3 . . . .
## DA Miller       . . . . . 3 . . . .
#Plot ratings
image(r0, main = "Raw Ratings")
#Plot normalized ratings
r0_m <- normalize(r0)
getRatingMatrix(r0_m)[1:15,1:15]
## 15 x 15 sparse Matrix of class "dgCMatrix"
##    [[ suppressing 15 column names 'A Mishra', 'A Nortje', 'A Zampa' ... ]]
##                                                                       
## AB de Villiers   .         -0.7857143 -1.7857143 .  .       -1.7857143
## Abdul Samad      .          .          .         .  .        .        
## Abhishek Sharma  .          .          .         .  .        .        
## AD Russell      -2.6562500  .          .         .  .        .        
## AJ Finch         .          .          .         . -0.03125  .        
## AM Rahane        4.6041667  .          .         .  .       -1.3958333
## AR Patel         .          .          .         .  .        .        
## AT Rayudu       -2.1363636  .          .         .  .        .        
## B Kumar          0.3636364  .          0.3636364 .  .        .        
## BA Stokes        .          .          .         .  .        .        
## CA Lynn          .          .          .         .  .        .        
## CH Gayle         .          .          .         .  .        1.5476190
## CH Morris        .          0.3500000  .         .  .        .        
## D Padikkal       .          0.6250000  .         .  .       -0.3750000
## DA Miller        .          .          .         .  .       -0.7037037
##                                                                              
## AB de Villiers   .         -1.7857143 . . . -0.7857143 -1.785714  .         .
## Abdul Samad      .          .         . . .  .          .         .         .
## Abhishek Sharma  .          .         . . . -1.6000000  .         .         .
## AD Russell       .          2.3437500 . . . -0.6562500 -0.656250 -0.6562500 .
## AJ Finch         .          .         . . . -2.0312500  .         .         .
## AM Rahane        .         -1.3958333 . . . -1.3958333 -1.395833  .         .
## AR Patel         .         -2.3333333 . . .  .          .         .         .
## AT Rayudu       -3.1363636  .         . . . -1.1363636  .         .         .
## B Kumar          .          .         . . .  .          .         0.3636364 .
## BA Stokes       -0.6086957  0.3913043 . . . -0.6086957  .         .         .
## CA Lynn          .          5.3200000 . . . -0.6800000  .         .         .
## CH Gayle         .         -1.4523810 . . .  1.5476190  .         .         .
## CH Morris        .          .         . . .  0.3500000  .         .         .
## D Padikkal       .          .         . . .  .         -0.375000  .         .
## DA Miller        .          .         . . . -0.7037037  .         .         .
image(r0_m, main = "Normalized Ratings")
set.seed(1234)
hist(getRatings(r0), breaks=25)
hist(getRatings(r0_m), breaks=25)

4a. Data for analysis

The data frame of the batsman vs bowlers from the period 2020 -2022 is read as a dataframe. To remove rows with very low number of ratings(timesOut, SR, Fours, Sixes etc), the rows are filtered so that there are at least more 10 values in the row. For the player estimation the dataframe is converted into a wide-format as a matrix (m x n) of batsman x bowler with each of the columns of the dataframe i.e. timesOut, SR, fours or sixes. These different matrices can be considered as a rating matrix for estimation.

A similar approach is taken for estimating bowler performance. Here a wide form matrix (m x n) of bowler x batsman is created for each of the columns of deliveries, runsConceded, ER, wicketsTaken

5. Batsman’s times Out

The code below estimates the number of times the batsmen would lose his/her wicket to the bowler. As discussed in the algorithm above, the recommendation engine will make an initial estimate features for the bowler and an initial estimate for the parameter vector for the batsmen. Then using gradient descent the recommender engine will determine the feature and parameter values such that the over Mean Squared Error is minimum

From the plot for the different algorithms it can be seen that UBCF performs the best. However the AUC & ROC curves are not optimal and the AUC> 0.5

df3 <- select(df, batsman1,bowler1,timesOut)
df6 <- xtabs(timesOut ~ ., df3)
df7 <- as.data.frame.matrix(df6)
df8 <- data.matrix(df7)
df8[df8 == 0] <- NA
r <- as(df8,"realRatingMatrix")
# Filter only rows where the row count is > 10
r0=r[(rowCounts(r) > 10),]
getRatingMatrix(r0)[1:10,1:10]
## 10 x 10 sparse Matrix of class "dgCMatrix"
##    [[ suppressing 10 column names 'A Mishra', 'A Nortje', 'A Zampa' ... ]]
##                                    
## AB de Villiers  . 4 3 . . 3 . 3 . .
## Abdul Samad     . . . . . . . . . .
## Abhishek Sharma . . . . . . . . . .
## AD Russell      1 . . . . . . 6 . .
## AJ Finch        . . . . 3 . . . . .
## AM Rahane       9 . . . . 3 . 3 . .
## AR Patel        . . . . . . . 1 . .
## AT Rayudu       2 . . . . . 1 . . .
## B Kumar         3 . 3 . . . . . . .
## BA Stokes       . . . . . . 3 4 . .
summary(getRatings(r0))
##    Min. 1st Qu.  Median    Mean 3rd Qu.    Max. 
##   1.000   3.000   3.000   3.463   4.000  21.000
# Evaluate the different plotting methods
evalRecomMethods(r0[1:dim(r0)[1]],k1=5,given=7,goodRating1=median(getRatings(r0)))
#Evaluate the error
a=eval(r0[1:dim(r0)[1]],0.8,k1=5,given1=7,goodRating1=median(getRatings(r0)),"UBCF")
## Recommender of type 'UBCF' for 'realRatingMatrix' 
## learned using 70 users.
## 18 x 145 rating matrix of class 'realRatingMatrix' with 1755 ratings.
##     RMSE      MSE      MAE 
## 2.069027 4.280872 1.496388
b=round(as(a,"matrix")[1:10,1:10])
c <- as(b,"realRatingMatrix")
m=as(c,"data.frame")
names(m) =c("batsman","bowler","TimesOut")

6. Batsman’s Strike rate

This section deals with the Strike rate of batsmen versus bowlers and estimates the values for those where the data is incomplete using UBCF method.

Even here all the algorithms do not perform too efficiently. I did try out a few variations but could not lower the error (suggestions welcome!!)

df3 <- select(df, batsman1,bowler1,SR)
df6 <- xtabs(SR ~ ., df3)
df7 <- as.data.frame.matrix(df6)
df8 <- data.matrix(df7)
df8[df8 == 0] <- NA
r <- as(df8,"realRatingMatrix")
r0=r[(rowCounts(r) > 10),]
getRatingMatrix(r0)[1:10,1:10]
## 10 x 10 sparse Matrix of class "dgCMatrix"
##    [[ suppressing 10 column names 'A Mishra', 'A Nortje', 'A Zampa' ... ]]
##                                                                           
## AB de Villiers   96.8254 171.4286  33.33333  . 66.66667 223.07692   .     
## Abdul Samad       .      228.0000   .        .  .       100.00000   .     
## Abhishek Sharma 150.0000   .        .        .  .        66.66667   .     
## AD Russell      111.4286   .        .        .  .         .         .     
## AJ Finch        250.0000 116.6667   .        . 50.00000  85.71429 112.5000
## AJ Tye            .        .        .        .  .         .       100.0000
## AK Markram        .        .        .       50  .         .         .     
## AM Rahane       121.1111   .        .        .  .       113.82979 117.9487
## AR Patel        183.3333   .      200.00000  .  .       433.33333   .     
## AT Rayudu       126.5432 200.0000 122.22222  .  .       105.55556   .     
##                                
## AB de Villiers  109.52381 .   .
## Abdul Samad       .       .   .
## Abhishek Sharma   .       .   .
## AD Russell      195.45455 .   .
## AJ Finch          .       .   .
## AJ Tye            .       .   .
## AK Markram        .       .   .
## AM Rahane        33.33333 . 200
## AR Patel        171.42857 .   .
## AT Rayudu       204.76190 .   .
summary(getRatings(r0))
##    Min. 1st Qu.  Median    Mean 3rd Qu.    Max. 
##   5.882  85.714 116.667 128.529 160.606 600.000
evalRecomMethods(r0[1:dim(r0)[1]],k1=5,given=7,goodRating1=median(getRatings(r0)))
a=eval(r0[1:dim(r0)[1]],0.8, k1=5,given1=7,goodRating1=median(getRatings(r0)),"UBCF")
## Recommender of type 'UBCF' for 'realRatingMatrix' 
## learned using 105 users.
## 27 x 145 rating matrix of class 'realRatingMatrix' with 3220 ratings.
##       RMSE        MSE        MAE 
##   77.71979 6040.36508   58.58484
b=round(as(a,"matrix")[1:10,1:10])
c <- as(b,"realRatingMatrix")
n=as(c,"data.frame")
names(n) =c("batsman","bowler","SR")

7. Batsman’s Sixes

The snippet of code estimes the sixes of the batsman against bowlers. The ROC and AUC curve for UBCF looks a lot better here, as it significantly greater than 0.5

df3 <- select(df, batsman1,bowler1,sixes)
df6 <- xtabs(sixes ~ ., df3)
df7 <- as.data.frame.matrix(df6)
df8 <- data.matrix(df7)
df8[df8 == 0] <- NA
r <- as(df8,"realRatingMatrix")
r0=r[(rowCounts(r) > 10),]
getRatingMatrix(r0)[1:10,1:10]
## 10 x 10 sparse Matrix of class "dgCMatrix"
##    [[ suppressing 10 column names 'A Mishra', 'A Nortje', 'A Zampa' ... ]]
##                                      
## AB de Villiers  3 3 . . . 18 .  3 . .
## AD Russell      3 . . . .  . . 12 . .
## AJ Finch        2 . . . .  . .  . . .
## AM Rahane       7 . . . .  3 1  . . .
## AR Patel        4 . 3 . .  6 .  1 . .
## AT Rayudu       5 2 . . .  . .  1 . .
## BA Stokes       . . . . .  . .  . . .
## CA Lynn         . . . . .  . .  9 . .
## CH Gayle       17 . . . . 17 .  . . .
## CH Morris       . . 3 . .  . .  . . .
summary(getRatings(r0))
##    Min. 1st Qu.  Median    Mean 3rd Qu.    Max. 
##    1.00    3.00    3.00    4.68    6.00   33.00
evalRecomMethods(r0[1:dim(r0)[1]],k1=5,given=7,goodRating1=median(getRatings(r0)))
## Timing stopped at: 0.003 0 0.002
a=eval(r0[1:dim(r0)[1]],0.8, k1=5,given1=7,goodRating1=median(getRatings(r0)),"UBCF")
## Recommender of type 'UBCF' for 'realRatingMatrix' 
## learned using 52 users.
## 14 x 145 rating matrix of class 'realRatingMatrix' with 1634 ratings.
##      RMSE       MSE       MAE 
##  3.529922 12.460350  2.532122
b=round(as(a,"matrix")[1:10,1:10])
c <- as(b,"realRatingMatrix")
o=as(c,"data.frame")
names(o) =c("batsman","bowler","Sixes")

8. Batsman’s Fours

The code below estimates 4s for the batsmen

df3 <- select(df, batsman1,bowler1,fours)
df6 <- xtabs(fours ~ ., df3)
df7 <- as.data.frame.matrix(df6)
df8 <- data.matrix(df7)
df8[df8 == 0] <- NA
r <- as(df8,"realRatingMatrix")
r0=r[(rowCounts(r) > 10),]
getRatingMatrix(r0)[1:10,1:10]
## 10 x 10 sparse Matrix of class "dgCMatrix"
##    [[ suppressing 10 column names 'A Mishra', 'A Nortje', 'A Zampa' ... ]]
##                                      
## AB de Villiers   . 1 . . . 24 . 3 . .
## Abhishek Sharma  . . . . .  . . . . .
## AD Russell       1 . . . .  . . 9 . .
## AJ Finch         . 1 . . .  3 2 . . .
## AK Markram       . . . . .  . . . . .
## AM Rahane       11 . . . .  8 7 . . 3
## AR Patel         . . . . .  . . 3 . .
## AT Rayudu       11 2 3 . .  6 . 6 . .
## BA Stokes        1 . . . .  . . . . .
## CA Lynn          . . . . .  . . 6 . .
summary(getRatings(r0))
##    Min. 1st Qu.  Median    Mean 3rd Qu.    Max. 
##   1.000   3.000   4.000   6.339   9.000  55.000
evalRecomMethods(r0[1:dim(r0)[1]],k1=5,given=7,goodRating1=median(getRatings(r0)))
## Timing stopped at: 0.008 0 0.008
## Warning in .local(x, method, ...): 
##   Recommender 'UBCF Pearson' has failed and has been removed from the results!
a=eval(r0[1:dim(r0)[1]],0.8, k1=5,given1=7,goodRating1=median(getRatings(r0)),"UBCF")
## Recommender of type 'UBCF' for 'realRatingMatrix' 
## learned using 67 users.
## 17 x 145 rating matrix of class 'realRatingMatrix' with 2083 ratings.
##      RMSE       MSE       MAE 
##  5.486661 30.103447  4.060990
b=round(as(a,"matrix")[1:10,1:10])
c <- as(b,"realRatingMatrix")
p=as(c,"data.frame")
names(p) =c("batsman","bowler","Fours")

9. Batsman’s Total Runs

The code below estimates the total runs that would have scored by the batsman against different bowlers

df3 <- select(df, batsman1,bowler1,totalRuns)
df6 <- xtabs(totalRuns ~ ., df3)
df7 <- as.data.frame.matrix(df6)
df8 <- data.matrix(df7)
df8[df8 == 0] <- NA
r <- as(df8,"realRatingMatrix")
r0=r[(rowCounts(r) > 10),]
getRatingMatrix(r)[1:10,1:10]
## 10 x 10 sparse Matrix of class "dgCMatrix"
##    [[ suppressing 10 column names 'A Mishra', 'A Nortje', 'A Zampa' ... ]]
##                                          
## A Badoni         .  . . . .   . .   . . .
## A Manohar        .  . . . .   . .   . . .
## A Nortje         .  . . . .   . .   . . .
## AB de Villiers  61 36 3 . 6 261 .  69 . .
## Abdul Samad      . 57 . . .  12 .   . . .
## Abhishek Sharma  3  . . . .   6 .   . . .
## AD Russell      39  . . . .   . . 129 . .
## AF Milne         .  . . . .   . .   . . .
## AJ Finch        15  7 . . 3  18 9   . . .
## AJ Tye           .  . . . .   . 4   . . .
summary(getRatings(r0))
##    Min. 1st Qu.  Median    Mean 3rd Qu.    Max. 
##    1.00    9.00   24.00   41.36   54.00  452.00
evalRecomMethods(r0[1:dim(r0)[1]],k1=5,given1=7,goodRating1=median(getRatings(r0)))
a=eval(r0[1:dim(r0)[1]],0.8, k1=5,given1=7,goodRating1=median(getRatings(r0)),"UBCF")
## Recommender of type 'UBCF' for 'realRatingMatrix' 
## learned using 105 users.
## 27 x 145 rating matrix of class 'realRatingMatrix' with 3256 ratings.
##       RMSE        MSE        MAE 
##   41.50985 1723.06788   29.52958
b=round(as(a,"matrix")[1:10,1:10])
c <- as(b,"realRatingMatrix")
q=as(c,"data.frame")
names(q) =c("batsman","bowler","TotalRuns")

10. Batsman’s Balls Faced

The snippet estimates the balls faced by batsmen versus bowlers

df3 <- select(df, batsman1,bowler1,ballsFaced)
df6 <- xtabs(ballsFaced ~ ., df3)
df7 <- as.data.frame.matrix(df6)
df8 <- data.matrix(df7)
df8[df8 == 0] <- NA
r <- as(df8,"realRatingMatrix")
r0=r[(rowCounts(r) > 10),]
getRatingMatrix(r)[1:10,1:10]
## 10 x 10 sparse Matrix of class "dgCMatrix"
##    [[ suppressing 10 column names 'A Mishra', 'A Nortje', 'A Zampa' ... ]]
##                                         
## A Badoni         .  . . . .   . .  . . .
## A Manohar        .  . . . .   . .  . . .
## A Nortje         .  . . . .   . .  . . .
## AB de Villiers  63 21 9 . 9 117 . 63 . .
## Abdul Samad      . 25 . . .  12 .  . . .
## Abhishek Sharma  2  . . . .   9 .  . . .
## AD Russell      35  . . . .   . . 66 . .
## AF Milne         .  . . . .   . .  . . .
## AJ Finch         6  6 . . 6  21 8  . . .
## AJ Tye           .  . . . .   9 4  . . .
summary(getRatings(r0))
##    Min. 1st Qu.  Median    Mean 3rd Qu.    Max. 
##    1.00    9.00   18.00   30.21   39.00  384.00
evalRecomMethods(r0[1:dim(r0)[1]],k1=5,given=7,goodRating1=median(getRatings(r0)))
a=eval(r0[1:dim(r0)[1]],0.8, k1=5,given1=7,goodRating1=median(getRatings(r0)),"UBCF")
## Recommender of type 'UBCF' for 'realRatingMatrix' 
## learned using 112 users.
## 28 x 145 rating matrix of class 'realRatingMatrix' with 3378 ratings.
##       RMSE        MSE        MAE 
##   33.91251 1150.05835   23.39439
b=round(as(a,"matrix")[1:10,1:10])
c <- as(b,"realRatingMatrix")
r=as(c,"data.frame")
names(r) =c("batsman","bowler","BallsFaced")

11. Generate the Batsmen Performance Estimate

This code generates the estimated dataframe with known and ‘predicted’ values

a1=merge(m,n,by=c("batsman","bowler"))
a2=merge(a1,o,by=c("batsman","bowler"))
a3=merge(a2,p,by=c("batsman","bowler"))
a4=merge(a3,q,by=c("batsman","bowler"))
a5=merge(a4,r,by=c("batsman","bowler"))
a6= select(a5, batsman,bowler,BallsFaced,TotalRuns,Fours, Sixes, SR,TimesOut)
head(a6)
##          batsman          bowler BallsFaced TotalRuns Fours Sixes  SR TimesOut
## 1 AB de Villiers        A Mishra         94       124     7     5 144        5
## 2 AB de Villiers        A Nortje         26        42     4     3 148        3
## 3 AB de Villiers         A Zampa         28        42     5     7 106        4
## 4 AB de Villiers Abhishek Sharma         22        28     0    10 136        5
## 5 AB de Villiers      AD Russell         70       135    14    12 207        4
## 6 AB de Villiers        AF Milne         31        45     6     6 130        3

12. Bowler analysis

Just like the batsman performance estimation we can consider the bowler’s performances also for estimation. Consider the following table

As in the batsman analysis, for every batsman a set of features like (“strong backfoot player”, “360 degree player”,“Power hitter”) can be estimated with a set of initial values. Also every bowler will have an associated parameter vector θθ. Different bowlers will have performance data for different set of batsmen. Based on the initial estimate of the features and the parameters, gradient descent can be used to minimize actual values {for e.g. wicketsTaken(ratings)}.

load("recom_data/bowlerVsBatsman20_22.rdata")

12a. Bowler dataframe

Inspecting the bowler dataframe

head(df2)
##    bowler1        batsman1 balls runsConceded       ER wicketTaken
## 1 A Mishra        A Badoni     0            0 0.000000           0
## 2 A Mishra       A Manohar     0            0 0.000000           0
## 3 A Mishra        A Nortje     0            0 0.000000           0
## 4 A Mishra  AB de Villiers    63           61 5.809524           0
## 5 A Mishra     Abdul Samad     0            0 0.000000           0
## 6 A Mishra Abhishek Sharma     2            3 9.000000           0
names(df2)
## [1] "bowler1"      "batsman1"     "balls"        "runsConceded" "ER"          
## [6] "wicketTaken"

13. Balls bowled by bowler

The below section estimates the balls bowled for each bowler. We can see that UBCF Pearson and UBCF Cosine both perform well

df3 <- select(df2, bowler1,batsman1,balls)
df6 <- xtabs(balls ~ ., df3)
df7 <- as.data.frame.matrix(df6)
df8 <- data.matrix(df7)
df8[df8 == 0] <- NA
r <- as(df8,"realRatingMatrix")
r0=r[(rowCounts(r) > 10),]
getRatingMatrix(r0)[1:10,1:10]
## 10 x 10 sparse Matrix of class "dgCMatrix"
##    [[ suppressing 10 column names 'A Badoni', 'A Manohar', 'A Nortje' ... ]]
##                                          
## A Mishra        . . .  63  .  2 35 .  6 .
## A Nortje        . . .  21 25  .  . .  6 .
## A Zampa         . . .   9  .  .  . .  . .
## Abhishek Sharma . . .   9  .  .  . .  6 .
## AD Russell      . . . 117 12  9  . . 21 9
## AF Milne        . . .   .  .  .  . .  8 4
## AJ Tye          . . .  63  .  . 66 .  . .
## Akash Deep      . . .   .  .  .  . .  . .
## AR Patel        . . . 188  5  1 84 . 29 5
## Arshdeep Singh  . . .   6  6 24 18 . 12 .
summary(getRatings(r0))
##    Min. 1st Qu.  Median    Mean 3rd Qu.    Max. 
##    1.00    9.00   18.00   29.61   36.00  384.00
evalRecomMethods(r0[1:dim(r0)[1]],k1=5,given=7,goodRating1=median(getRatings(r0)))
a=eval(r0[1:dim(r0)[1]],0.8,k1=5,given1=7,goodRating1=median(getRatings(r0)),"UBCF")
## Recommender of type 'UBCF' for 'realRatingMatrix' 
## learned using 96 users.
## 24 x 195 rating matrix of class 'realRatingMatrix' with 3954 ratings.
##      RMSE       MSE       MAE 
##  30.72284 943.89294  19.89204
b=round(as(a,"matrix")[1:10,1:10])
c <- as(b,"realRatingMatrix")
s=as(c,"data.frame")
names(s) =c("bowler","batsman","BallsBowled")

14. Runs conceded by bowler

This section estimates the runs conceded by the bowler. The UBCF Cosinus algorithm performs the best with TPR increasing fastewr than FPR

df3 <- select(df2, bowler1,batsman1,runsConceded)
df6 <- xtabs(runsConceded ~ ., df3)
df7 <- as.data.frame.matrix(df6)
df8 <- data.matrix(df7)
df8[df8 == 0] <- NA
r <- as(df8,"realRatingMatrix")
r0=r[(rowCounts(r) > 10),]
getRatingMatrix(r0)[1:10,1:10]
## 10 x 10 sparse Matrix of class "dgCMatrix"
##    [[ suppressing 10 column names 'A Badoni', 'A Manohar', 'A Nortje' ... ]]
##                                            
## A Mishra        . . .  61  .  3  41 . 15  .
## A Nortje        . . .  36 57  .   . .  8  .
## A Zampa         . . .   3  .  .   . .  .  .
## Abhishek Sharma . . .   6  .  .   . .  3  .
## AD Russell      . . . 276 12  6   . . 21  .
## AF Milne        . . .   .  .  .   . . 10  4
## AJ Tye          . . .  69  .  . 138 .  .  .
## Akash Deep      . . .   .  .  .   . .  .  .
## AR Patel        . . . 205  5  . 165 . 33 13
## Arshdeep Singh  . . .  18  3 51  51 .  6  .
summary(getRatings(r0))
##    Min. 1st Qu.  Median    Mean 3rd Qu.    Max. 
##    1.00    9.00   24.00   41.34   54.00  458.00
evalRecomMethods(r0[1:dim(r0)[1]],k1=5,given=7,goodRating1=median(getRatings(r0)))
## Timing stopped at: 0.004 0 0.004
## Warning in .local(x, method, ...): 
##   Recommender 'UBCF Pearson' has failed and has been removed from the results!
a=eval(r0[1:dim(r0)[1]],0.8,k1=5,given1=7,goodRating1=median(getRatings(r0)),"UBCF")
## Recommender of type 'UBCF' for 'realRatingMatrix' 
## learned using 95 users.
## 24 x 195 rating matrix of class 'realRatingMatrix' with 3820 ratings.
##       RMSE        MSE        MAE 
##   43.16674 1863.36749   30.32709
b=round(as(a,"matrix")[1:10,1:10])
c <- as(b,"realRatingMatrix")
t=as(c,"data.frame")
names(t) =c("bowler","batsman","RunsConceded")

15. Economy Rate of the bowler

This section computes the economy rate of the bowler. The performance is not all that good

df3 <- select(df2, bowler1,batsman1,ER)
df6 <- xtabs(ER ~ ., df3)
df7 <- as.data.frame.matrix(df6)
df8 <- data.matrix(df7)
df8[df8 == 0] <- NA
r <- as(df8,"realRatingMatrix")
r0=r[(rowCounts(r) > 10),]
getRatingMatrix(r0)[1:10,1:10]
## 10 x 10 sparse Matrix of class "dgCMatrix"
##    [[ suppressing 10 column names 'A Badoni', 'A Manohar', 'A Nortje' ... ]]
##                                                                       
## A Mishra        . . .  5.809524  .     9.00  7.028571 . 15.000000  .  
## A Nortje        . . . 10.285714 13.68  .     .        .  8.000000  .  
## A Zampa         . . .  2.000000  .     .     .        .  .         .  
## Abhishek Sharma . . .  4.000000  .     .     .        .  3.000000  .  
## AD Russell      . . . 14.153846  6.00  4.00  .        .  6.000000  .  
## AF Milne        . . .  .         .     .     .        .  7.500000  6.0
## AJ Tye          . . .  6.571429  .     .    12.545455 .  .         .  
## Akash Deep      . . .  .         .     .     .        .  .         .  
## AR Patel        . . .  6.542553  6.00  .    11.785714 .  6.827586 15.6
## Arshdeep Singh  . . . 18.000000  3.00 12.75 17.000000 .  3.000000  .
summary(getRatings(r0))
##    Min. 1st Qu.  Median    Mean 3rd Qu.    Max. 
##  0.3529  5.2500  7.1126  7.8139  9.8000 36.0000
evalRecomMethods(r0[1:dim(r0)[1]],k1=5,given=7,goodRating1=median(getRatings(r0)))
## Timing stopped at: 0.003 0 0.004
## Warning in .local(x, method, ...): 
##   Recommender 'UBCF Pearson' has failed and has been removed from the results!
a=eval(r0[1:dim(r0)[1]],0.8,k1=5,given1=7,goodRating1=median(getRatings(r0)),"UBCF")
## Recommender of type 'UBCF' for 'realRatingMatrix' 
## learned using 95 users.
## 24 x 195 rating matrix of class 'realRatingMatrix' with 3839 ratings.
##      RMSE       MSE       MAE 
##  4.380680 19.190356  3.316556
b=round(as(a,"matrix")[1:10,1:10])
c <- as(b,"realRatingMatrix")
u=as(c,"data.frame")
names(u) =c("bowler","batsman","EconomyRate")

16. Wickets Taken by bowler

The code below computes the wickets taken by the bowler versus different batsmen

df3 <- select(df2, bowler1,batsman1,wicketTaken)
df6 <- xtabs(wicketTaken ~ ., df3)
df7 <- as.data.frame.matrix(df6)
df8 <- data.matrix(df7)
df8[df8 == 0] <- NA
r <- as(df8,"realRatingMatrix")
r0=r[(rowCounts(r) > 10),]
getRatingMatrix(r0)[1:10,1:10]
## 10 x 10 sparse Matrix of class "dgCMatrix"
##    [[ suppressing 10 column names 'A Badoni', 'A Manohar', 'A Nortje' ... ]]
##                                   
## A Mishra       . . . . . . 1 . . .
## A Nortje       . . . 4 . . . . . .
## A Zampa        . . . 3 . . . . . .
## AD Russell     . . . 3 . . . . . .
## AJ Tye         . . . 3 . . 6 . . .
## AR Patel       . . . 4 . 1 3 . 1 1
## Arshdeep Singh . . . 3 . . 3 . . .
## AS Rajpoot     . . . . . . 3 . . .
## Avesh Khan     . . . . . . 1 . 3 .
## B Kumar        . . . 9 . . 3 . 1 .
summary(getRatings(r0))
##    Min. 1st Qu.  Median    Mean 3rd Qu.    Max. 
##   1.000   3.000   3.000   3.423   3.000  21.000
evalRecomMethods(r0[1:dim(r0)[1]],k1=5,given=7,goodRating1=median(getRatings(r0)))
## Timing stopped at: 0.003 0 0.003
## Warning in .local(x, method, ...): 
##   Recommender 'UBCF Pearson' has failed and has been removed from the results!
a=eval(r0[1:dim(r0)[1]],0.8,k1=5,given1=7,goodRating1=median(getRatings(r0)),"UBCF")
## Recommender of type 'UBCF' for 'realRatingMatrix' 
## learned using 64 users.
## 16 x 195 rating matrix of class 'realRatingMatrix' with 1908 ratings.
##     RMSE      MSE      MAE 
## 2.672677 7.143203 1.956934
b=round(as(a,"matrix")[1:10,1:10])
c <- as(b,"realRatingMatrix")
v=as(c,"data.frame")
names(v) =c("bowler","batsman","WicketTaken")

17. Generate the Bowler Performance estmiate

The entire dataframe is regenerated with known and ‘predicted’ values

r1=merge(s,t,by=c("bowler","batsman"))
r2=merge(r1,u,by=c("bowler","batsman"))
r3=merge(r2,v,by=c("bowler","batsman"))
r4= select(r3,bowler, batsman, BallsBowled,RunsConceded,EconomyRate, WicketTaken)
head(r4)
##     bowler         batsman BallsBowled RunsConceded EconomyRate WicketTaken
## 1 A Mishra  AB de Villiers         102          144           8           4
## 2 A Mishra     Abdul Samad          13           20           7           4
## 3 A Mishra Abhishek Sharma          14           26           8           2
## 4 A Mishra      AD Russell          47           85           9           3
## 5 A Mishra        AJ Finch          45           61          11           4
## 6 A Mishra          AJ Tye          14           20           5           4

18. Conclusion

This post showed an approach for performing the Batsmen Performance Estimate & Bowler Performance Estimate. The performance of the recommender engine could have been better. In any case, I think this approach will work for player estimation provided the recommender algorithm is able to achieve a high degree of accuracy. This will be a good way to estimate as the algorithm will be able to determine features and nuances of batsmen and bowlers which cannot be captured by data.

References

  1. Recommender Systems – Machine Learning by Prof Andrew Ng
  2. recommenderlab: A Framework for Developing and Testing Recommendation Algorithms
  3. ROC 
  4. Precision-Recall

Also see

  1. Big Data 7: yorkr waltzes with Apache NiFi
  2. Benford’s law meets IPL, Intl. T20 and ODI cricket
  3. Using Linear Programming (LP) for optimizing bowling change or batting lineup in T20 cricket
  4. IPL 2022: Near real-time analytics with GooglyPlusPlus!!!
  5. Sixer
  6. Introducing cricpy:A python package to analyze performances of cricketers
  7. The Clash of the Titans in Test and ODI cricket
  8. Cricketr adds team analytics to its repertoire!!!
  9. Informed choices through Machine Learning – Analyzing Kohli, Tendulkar and Dravid
  10. Big Data 6: The T20 Dance of Apache NiFi and yorkpy

To see all posts click Index of posts